 Non
Demos
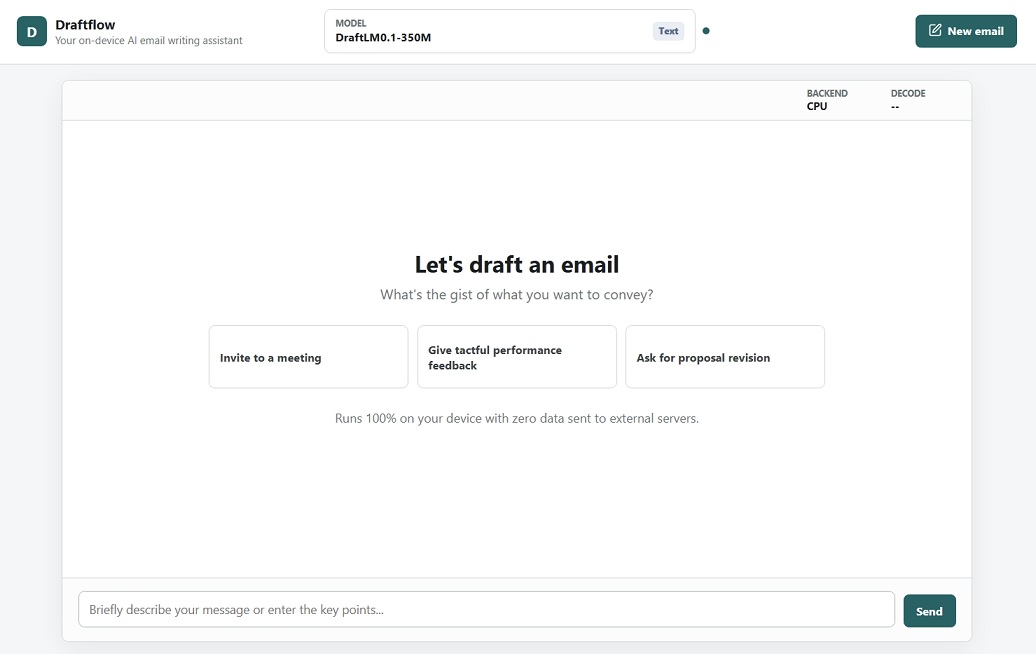
Draftflow ➡
Can a language model run on modest hardware and still be practically useful? Draftflow is a proof of concept I built as part of exploring this question.
It's an email drafting assistant that runs entirely on CPU in your browser. Jot a terse, messenger-style note and Draftflow returns a full draft plus a few writing tips. Setup is zero: you open a page and it runs.
Under the hood there's a task-specific 350M parameter language model I fine-tuned on a custom semi-synthetic data mixture. The base model is LFM2.5-350M by Liquid AI. Browser inference is powered by llama.cpp and Sipp.
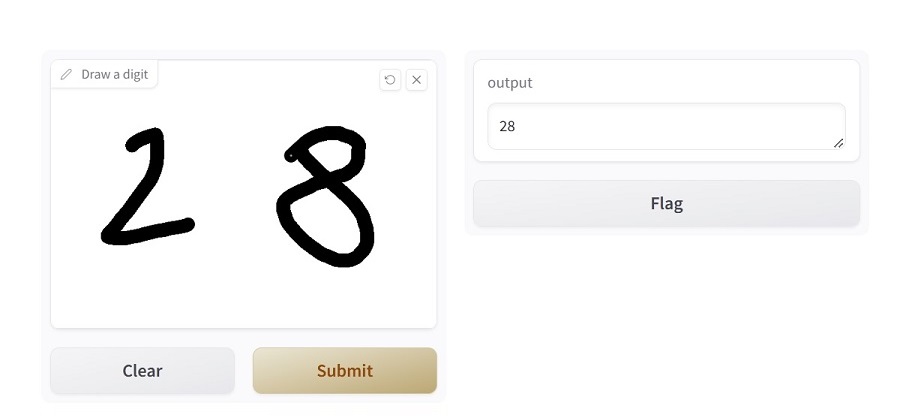
Perceptron at (nearly) 70 ➡
How would Frank Rosenblatt’s perceptron (1958) fare had Frank been given backpropagation, gradient descent, modern data augmentation techniques and hardware? I made this demo to investigate.
It runs a two-hidden-layer perceptron that recognizes the digits you draw. Inference takes milliseconds on a modest CPU and the entire Docker image fits into 250MB of RAM. See if you can fool it with a digit humans would have no trouble recognizing :)